AI Product Engineer · Noida, India

I turn messy AI evaluation into decisions teams can trust.

Seven years building applied-AI platforms that convert complex evaluation and operational workflows into reliable, self-service products — at Adobe, PRISM and LLMJury do exactly that.

Ritesh Srivastava
75–90%
faster GenAI evaluation cycles
30×
faster than human review, +15% precision
100+
manual hours removed per cycle
13
locales certified across 2 pipelines
/ about

What I do

I build the tools that decide whether AI is ready to ship. My work sits at the seam between machine-learning evaluation and product delivery: taking ad hoc, spreadsheet-driven review and turning it into auditable, self-service systems that non-engineers can run and trust.

At Adobe I lead PRISM and LLMJury — an agentic release-certification platform and a multi-model evaluation framework. Before that I spent four years embedded with enterprise clients at TCS, shipping Python automation, Django systems, and data pipelines end to end.

/ experience

Where I've built

Adobe

Document Cloud & Artificial Intelligence

Noida, India

Lead Software Engineer

Jul 2025 — Present
  • Lead PRISM, an agentic release-certification platform that converts evaluation runs into auditable go/no-go decisions across 13 locales and 2 pipelines.
  • Automated per-locale evaluation reporting, replacing person-weeks of manual Excel scoring and cutting cycle time 75–90% (1–2 days to 3–4 hours).
  • Shipped a six-agent skill layer for Claude and Cursor so non-engineering stakeholders can run and interpret evaluations independently.
  • Implemented LLM-based triage and publish-isolation guardrails, halving confirmed regression-review volume while protecting shared W&B projects from cross-team corruption.

Senior Software Engineer

Apr 2022 — Jul 2025
  • Led LLMJury, a multi-model evaluation framework for GenAI summary, podcast, and assistant features, removing 100+ manual hours per evaluation cycle.
  • Turned ad hoc evaluation requests into self-service tooling adopted across the organization.
  • Built a Voxel51 and Labelbox analysis tool that cut manual evaluation effort 80%.

Tata Consultancy Services

Walgreens · Corteva/DuPont · Eaton

Noida, India

System Engineer

Nov 2018 — Apr 2022
  • Embedded with enterprise clients, gathering requirements and delivering production CRUD systems, Django automation, and REST APIs.
  • Built Python data-processing and automation workflows, including EDA pipelines and PySpark batch jobs.
/ projects

Things I've shipped

PRISM

75–90% faster cycles

Agentic release-certification platform

Converts evaluation runs into auditable go/no-go decisions: scoring, LLM triage, HTML reporting, Prefect and W&B orchestration, and publish-isolation guardrails.

  • Python
  • LLM eval
  • Prefect
  • Weights & Biases
  • Agents

LLMJury

30× faster, +15% precision

Multi-model GenAI evaluation framework

LLM-as-a-judge evaluation for summary, podcast, and assistant features — self-service tooling adopted across the org.

  • Python
  • LLM-as-a-judge
  • Prompt engineering

Voxel51 & Labelbox tooling

80% less manual effort

Dataset analysis & annotation workflow

Analysis tooling over Voxel51 and Labelbox that streamlined dataset review and annotation.

  • Python
  • Voxel51
  • Labelbox
/ toolkit

What I work with

Applied AI

  • Generative AI
  • LLM evaluation
  • LLM-as-a-judge
  • Agent & skill design
  • Prompt engineering

Engineering

  • Python
  • Django
  • REST APIs
  • SQL
  • PySpark
  • CLI tooling

Platform & delivery

  • Prefect
  • Weights & Biases
  • Docker
  • AWS
  • Git
  • Workflow automation

Product

  • Requirements discovery
  • Stakeholder management
  • Cross-team enablement
  • Technical documentation
/ off the clock

Off the clock

The version of me that isn't deciding whether some model is allowed to ship:

  • Builder by reflex. My own job hunt got tedious, so I built an agentic system to run it. This very site? Pair-programmed with an AI. If something annoys me, I'll usually automate it before I finish complaining.
  • Small-town Uttar Pradesh kid who wandered into applied AI and stayed. Now in Noida, mostly remote, happiest with a terminal open.
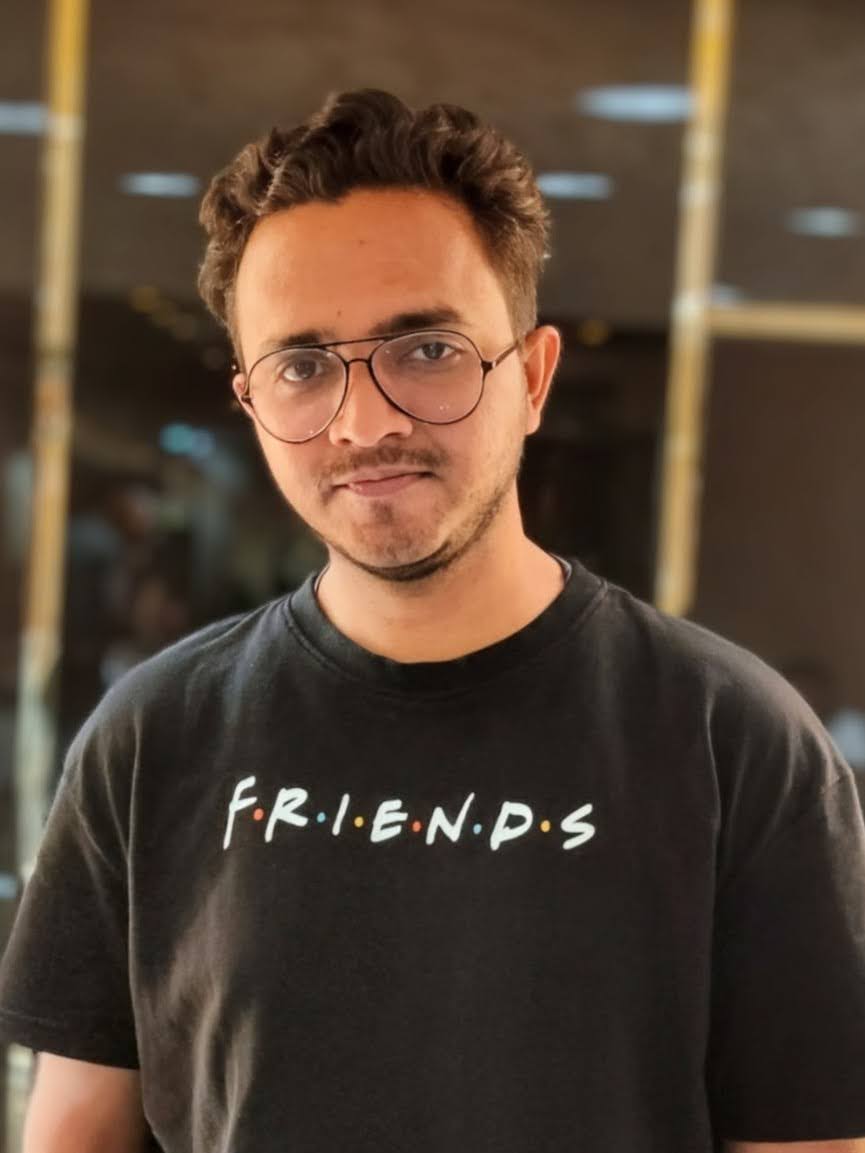
  • Will defend F.R.I.E.N.D.S as peak comfort TV — yes, that's the shirt. And no, they were not on a break.
  • Perpetual learner: always one course half-finished and one side project three commits deep.

If any of that resonates — or you just want to argue about Ross and Rachel — say hi below.

/ contact

Building something that needs AI you can actually trust?

I'm open to conversations about applied-AI, evaluation platforms, and forward-deployed engineering roles.

Prefer something direct?